Watch a Language Model Think
TokenPrint traces transformer inference as it happens. Follow tokens, tensors, attention, KV cache and generation through a real model.
Model Inspection
TokenPrint
Built for the moments that matter most.
Go beyond the output and inspect the computation behind it. TokenPrint lets you follow tokens, hidden states, attention, residual streams, and logits through a real transformer forward pass — making the model easier to understand, debug, and explore.
Real Model Execution
Trace real transformer execution from input tokens through embeddings, normalization, attention, MLPs, residual streams and logits.
Every Tensor, Inspectable
Inspect tensor shapes, parameters, hidden states, attention weights and model metadata directly inside the computation.
Token-by-Token Generation
Follow a token through the transformer during prefill and decode, with KV-cache state and operation progress visible as inference runs.
Attention Decoded
Explore Q, K and V projections, grouped-query attention, RoPE, attention scores and weighted values as the computation happens.
Token → Embedding
Tokens bind to an index and resolve into dense vectors.
Hidden State
Shapes, activations, and residual streams at every depth.
Attention
Q, K, and V projections and the scores that combine them.
Generation
Prefill, the KV cache, and logits choosing the next token.
Inspect what moves through the model.
Follow tokens, representations, and operations as they pass through every stage of inference.
See how a model thinks.
Follow the structures, tensors, and computations behind every prediction.
Understand the architecture
See how the model is organized from embeddings through transformer layers, residual streams, and the final prediction.
Understand the architecture
Inspect layers, tensors, residual streams, and model topology.
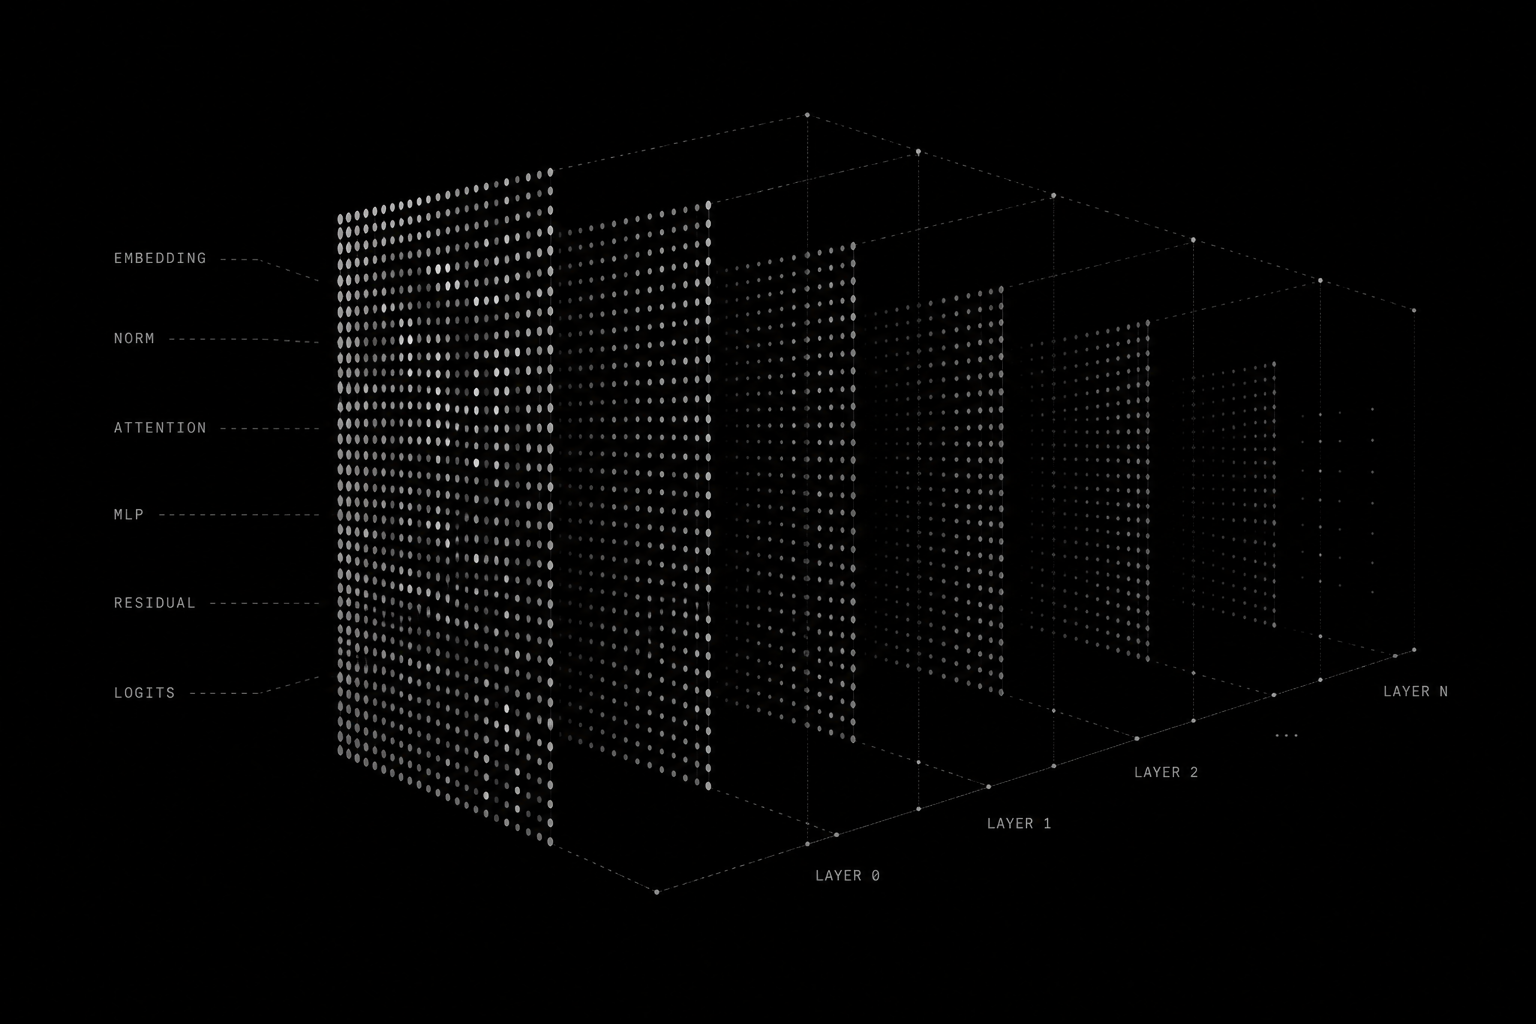
See attention unfold
Follow Q, K, and V through attention, from projections and positional encoding to scores, masking, and weighted values.
See attention unfold
Follow Q, K, V, attention scores, RoPE, and weighted values.
Watch generation happen
Follow the transition from prefill to decode as hidden states become logits, KV cache state, and the next generated token.
Watch generation happen
Trace prefill, KV cache, decoding, logits, and next-token prediction.
From token to prediction.
See what happens in between.
Every layer. Every tensor. Every step — open for inspection.
Contribute on GitHub→